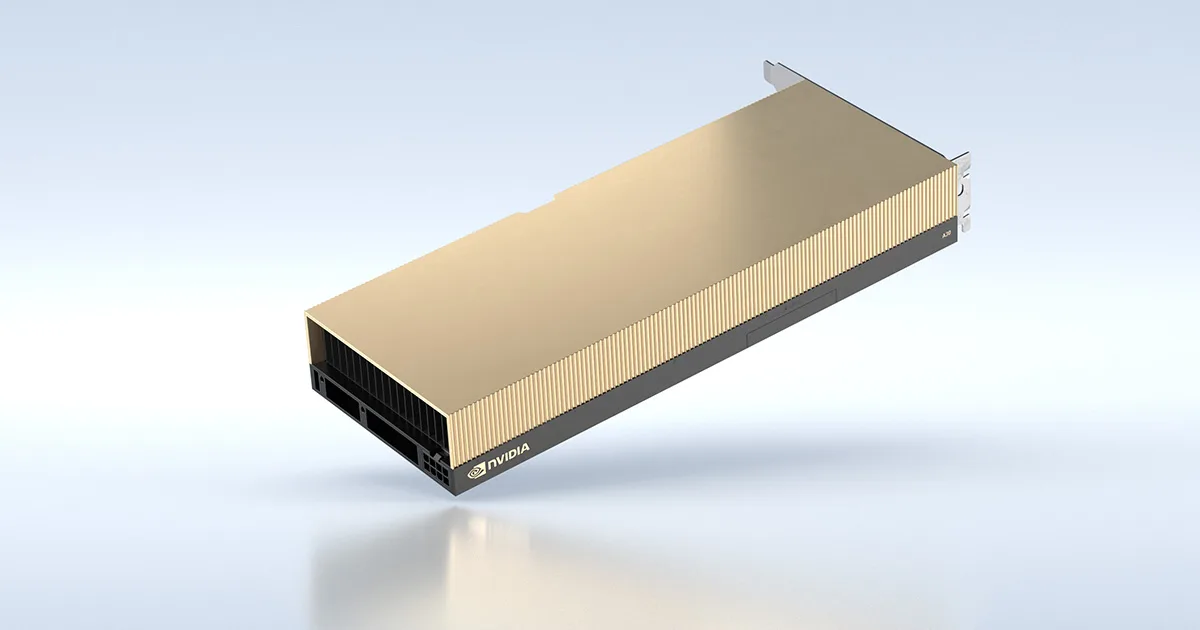
Image du produit à titre d'illustration ; la configuration peut différer.
NVIDIA A30 24 GB
Mainstream Ampere compute GPU with 24 GB HBM2 for inference and HPC.
| Interface | PCIe |
|---|---|
| Cooling | Passive (server airflow) |
| GPU memory | 24 GB HBM2 |
| Architecture | NVIDIA Ampere |
| Form factor | Dual-slot, full height, full length |
NVIDIA A30 24 GB est fabriqué sur commande et chiffré par projet (configuration, livraison, installation et support).
Testez un modèle sur nos machines avant d'acheter.
Choisissez le modèle et la quantification que vous comptez utiliser. Nous vous montrons s'il tient en mémoire, la place restante pour le contexte et le débit attendu. Les estimations reposent sur la bande passante mémoire et sont remplacées par nos propres mesures quand nous en avons.
Machine
Quantification
Confortable. 70 GB de marge — de la place pour un contexte de 128k, un deuxième petit modèle ou un index RAG en mémoire. Comptez environ 3.8 tok/s en flux unique.
Machines qui font tourner cette configuration
Poids 42.8 GB à 4.85 bits/paramètre · cache KV 5.0 GB à 16k (fp16, approximatif) · 10 GB réservés à l'OS et au runtime. La vitesse correspond au décodage en flux unique, limité par la mémoire ; le traitement du prompt et le batching se comportent différemment. Ou contactez un ingénieur sur WhatsApp au +44 7515 356 146.
A mid-range Ampere compute card with HBM2 memory, used for enterprise inference and HPC where an A100 is more than needed.
Fitted in a Workstation server or supplied standalone. Before it ships we check it against your chassis (power, airflow, risers, slot layout and NVIDIA-Certified status), burn-in test it and install drivers, CUDA, vGPU and NVIDIA AI Enterprise licensing where needed. Warranty claims and advance replacements are handled by us. Support comes from our own UK engineers, and Trade members get free tech support on every order.
Priced on quote: tell us what you need and we will confirm price, availability and lead time.