Deze gids is voorlopig alleen in het Engels beschikbaar.
Which workstation do I need to fine-tune AI models?
Fine-tuning teaches an existing model about your data, so it answers in your style and knows your field. Training needs far more memory than just running a model. The method you choose decides whether a single workstation is enough or you need a server.
Laatst gecontroleerd op 13 Oct 2026
Twijfelt u? Vraag het onze AI-adviseur
Vertel welk model, hoeveel data u hebt en wanneer u resultaten nodig hebt. Hij stelt alleen machines voor die wij verkopen, met echte prijzen en levertijden.
Pick the method first
- QLoRA: trains a small add-on while the main model stays compressed. Uses the least memory. A good start for most teams.
- LoRA: the same idea, without compressing the main model. A bit better quality, more memory.
- Full fine-tuning: changes every part of the model. Needs the most memory, usually several GPUs.
Rough GPU memory needed:
| Method | 7 to 8B model | 70B model |
|---|---|---|
| QLoRA | about 12 to 16 GB | about 48 GB or more |
| LoRA | about 24 GB | about 160 GB or more (several GPUs) |
| Full fine-tuning | about 130 GB or more (several GPUs) | 1 TB or more (GPU servers) |
These are rough guides. Longer training examples and bigger batches need more.
What else matters
- Fast storage: the GPUs should never wait for data. Use NVMe for the training set.
- System RAM: plan for at least twice your total GPU memory.
- Cooling and power: training runs for hours or days at full power. Every build we sell is checked for power, slots and cooling.
- Workstation or server: one to four GPUs fit in a desk-side workstation. Beyond that, a GPU server is quieter for the office and easier to share.
Workstations
Featured machines. Prices, stock and lead times are live.
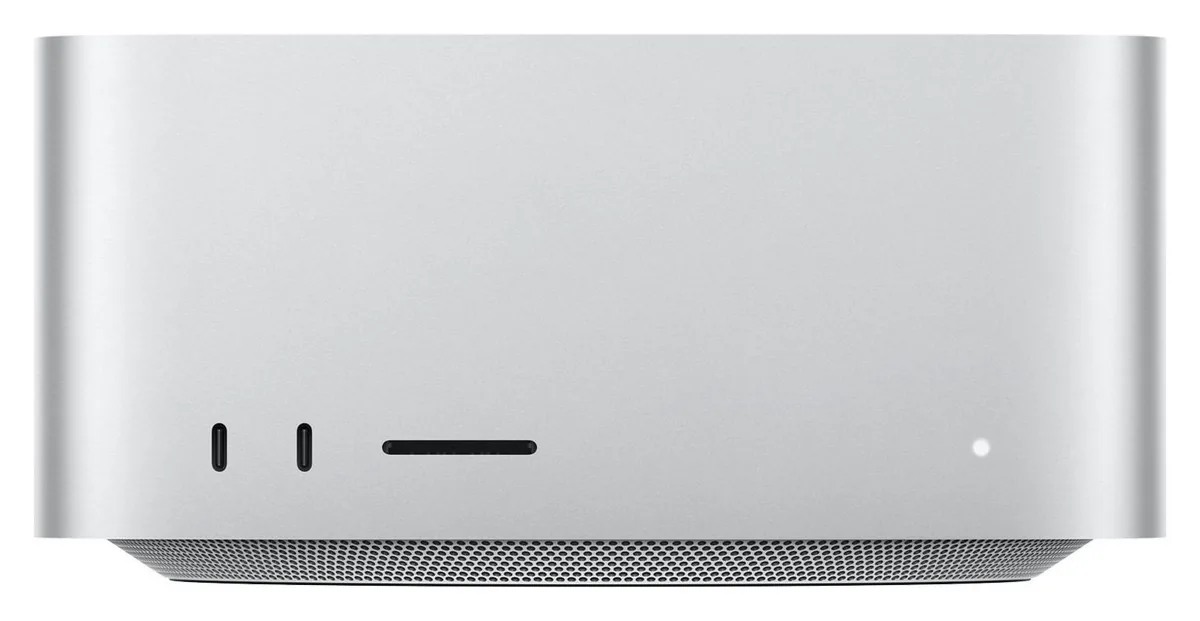
- Connectivity: 4× Thunderbolt 5 (rear), 10Gb Ethernet, Wi-Fi 7, Bluetooth 6
- Unified memory: 48 / 64 / 128 GB
- GPU: 40-core GPU with Neural Accelerators
- Connectivity: 4× Thunderbolt 5 (rear), 10Gb Ethernet, Wi-Fi 7, Bluetooth 6
- Unified memory: 96 / 256 GB (512 GB: see pre-order)
- GPU: 64- or 80-core GPU with Neural Accelerators

- CPU options: Threadripper PRO 9965WX / 9975WX / 9985WX / 9995WX
- Memory: 8-channel DDR5 ECC RDIMM, up to 1 TB as configured
- Platform: AMD WRX90
GPU servers
For full fine-tuning and shared training.
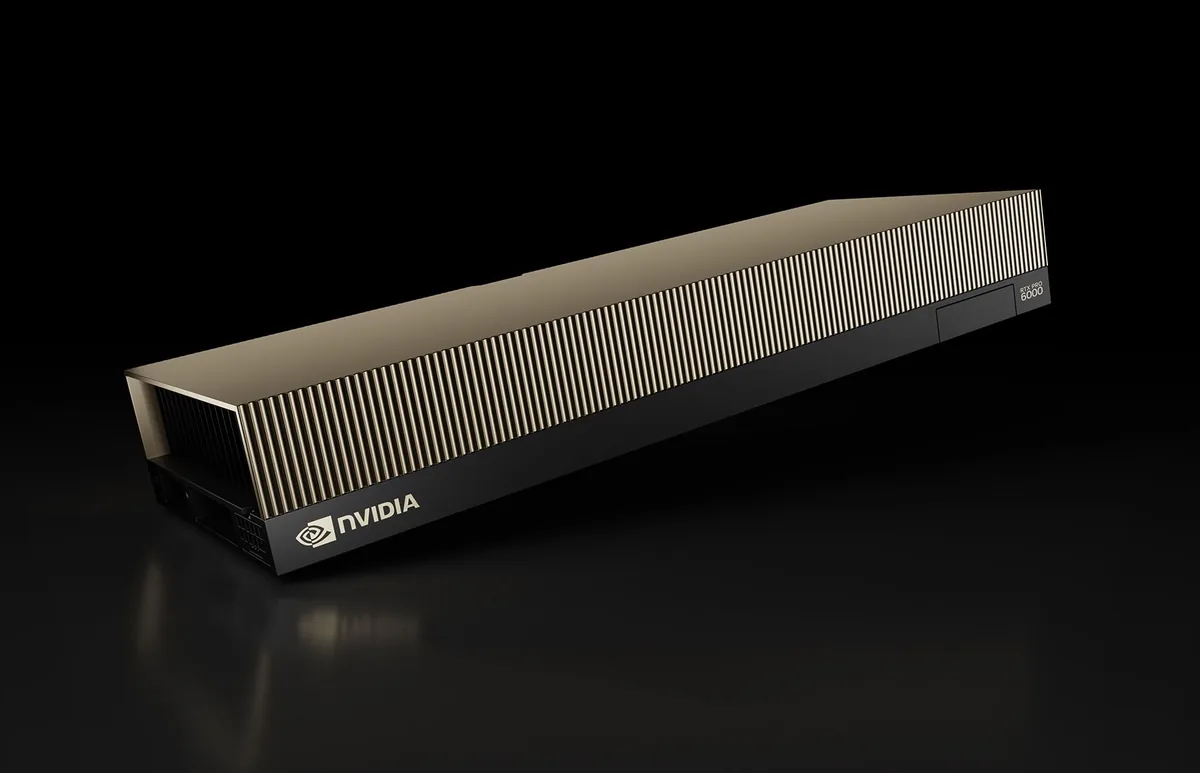
- GPU interface: PCIe 5.0 x16
- Memory: 24× DDR5 ECC RDIMM (12 channels per socket)
- CPU socket: 2× SP5
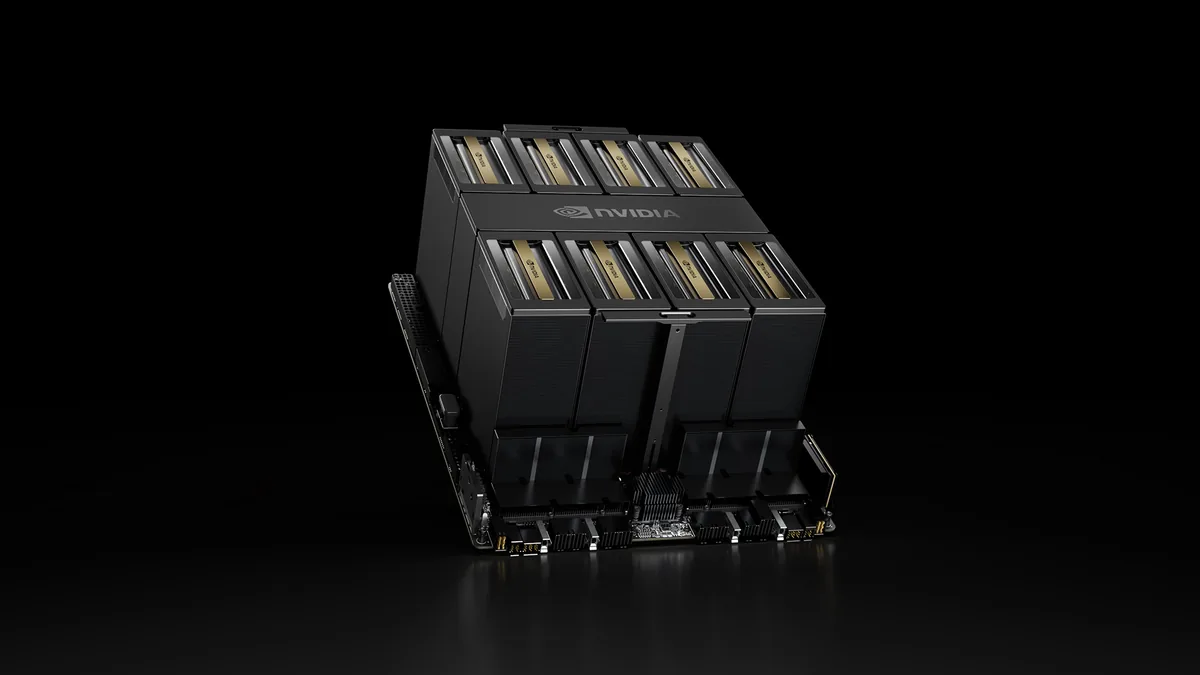
- Total GPU memory: 1.4 TB HBM3e
- GPU interconnect: Fifth-generation NVLink / NVSwitch
- GPUs: 8× NVIDIA B200

- Software: NVIDIA AI Enterprise, Omniverse
- Server platforms: Cisco, Dell, HPE, Lenovo, Supermicro
- Compute: NVIDIA-Certified RTX PRO servers or HGX B200 systems
Veelgestelde vragen
Can I fine-tune a 70B model on a workstation?
With QLoRA, yes, on a workstation with about 48 GB of GPU memory or more. Full fine-tuning of a 70B model needs GPU servers.
Are your prices shown with VAT?
Yes. Every price is shown without VAT and with VAT, and there are no hidden fees.
How long will it take to arrive?
Each product shows its real lead time from our stock data. The advisor uses the same data and won't guess a date.
Krijg een voorstel op maat van uw behoeften
Vertel welk model, hoeveel data u hebt en wanneer u resultaten nodig hebt. Hij stelt alleen machines voor die wij verkopen, met echte prijzen en levertijden.